English | 简体中文
Introduction
what-the-jev showcases what Jev (TypeSafe AI's "System One" decision model) can do across a wide range of tasks. This project provides a stable Jev experimentation framework for running tasks at scale with reproducible results. We use this framework to conduct experiments and provide reproducible results and analysis reports. example/ offers lightweight examples to help you get started, experiments/ provides complete experiments across different tasks with accompanying analysis reports, and resource/ catalogs Jev-related models, tools, and applications. Whether you are new to Jev or want to explore it in depth, this project is a good place to start.
Selected Findings
- Choosing the right agent skill: We tested whether Jev could choose a skill for a user request, or decide that no skill was needed, using a catalog of 126 real agent skills. Each of 250 tasks has a formal and a casual wording, giving 500 prompts. Jev answered 488 correctly (97.6%). Tasks requiring several skills chose from supplied skill combinations. Read the skill-routing experiment.
- Answering graduate-level science questions: We tested Jev on 198 biology, physics, and chemistry questions from GPQA Diamond, with four answer options per question. Jev answered 150 correctly (75.76%). Read the science-question experiment.
- Comparing housing prices: In the Boston Housing experiment, Jev correctly identified which of two suburbs had higher housing prices 88.2% of the time. Estimating a single suburb's price range was harder: converting its score into a price range was correct only 9.7% of the time; choosing the range it considered most likely reached 31.4%. Read the housing-price experiment.
Repository Structure
what-the-jev/
├── example/                            lightweight examples
│   ├── us-election/                    [History] Tests whether Jev can recall the winners of the eight US presidential elections from 1996 to 2024.
│   ├── math-word-problem/              [Arithmetic] Tests Jev on grade-school arithmetic word problems.
│   ├── university-math/                [Arithmetic] Tests Jev on calculus, linear algebra, and probability problems.
│   ├── pixel-recognition/              [Vision] Tests whether Jev can identify image content from raw pixel values alone.
│   ├── ethics-dilemmas/                [Ethics] Tests Jev's acceptability judgments in classic ethical dilemmas.
│   ├── prompt-injection-detection/     [Security] Tests whether Jev can detect prompt-injection attacks hidden in tool-call results.
│   ├── paper-qa/                       [Paper Reading] Tests whether Jev can answer questions about a research paper from only part of its text.
│   └── ticket-triage/                  [Business] Tests Jev's classification of customer-support tickets, refund claims, and urgency.
├── experiments/                        professional-grade experiments
│   ├── gpqa-diamond/                   [Benchmark] Explore JEV's performance on GPQA Diamond graduate-level science questions.
│   ├── gsm8k/                          [Benchmark] Explore JEV's performance on GSM8K grade-school math word problems.
│   ├── mmlu-pro/                       [Benchmark] Explore JEV's performance on MMLU-Pro college-level questions across 14 disciplines.
│   ├── bbq/                            [Benchmark] Explore JEV's performance on BBQ's bias-sensitive questions, and whether it leans toward stereotypes.
│   ├── socialiqa/                      [Benchmark] Explore JEV's performance on SocialIQA social commonsense questions.
│   ├── paper-classification/           [Paper Classification] Explore whether JEV can decide, based on a research preference, whether an arXiv paper belongs in a paper library, and which topic it falls under.
│   ├── paper-qa/                       [Paper QA] Explore whether JEV can answer questions about a paper based on its own text.
│   ├── prompt-routing/                 [Prompt Routing] Explore whether JEV can decide from the question text alone whether a question in paper QA goes to the JEV fast path or the LLM slow path.
│   ├── skill-routing/                  [Skill Routing] Explore whether JEV can route user tasks to the right skill, skill set, or none, among 126 real agent skills.
│   ├── boston-housing/                 [Numeric Regression] Explore whether JEV can predict Boston suburb housing prices, and compare price levels across suburbs.
│   ├── titanic/                        [Classification Prediction] Explore whether JEV can predict whether a Titanic passenger survived from the passenger record, and compare structured fields with prose text.
│   ├── dpo-jev-judge/                  [LLM Training] Explore JEV's performance on preference annotation for DPO training data.
│   └── grpo-jev-judge/                 [LLM Training] Explore JEV's performance on GRPO trajectory reward assignment.
├── resource/                           catalog of Jev-related projects and models
│   ├── closed-source-models/           [Closed-Source Models] Jev and its proprietary competitors
│   ├── open-source-models/             [Open-Source Models] open-weight decision models and replicas
│   ├── use-cases/                      [Use Cases] applications built with Jev
│   ├── integrations/                   [Integrations] gateways, frameworks, and platforms serving Jev
│   ├── tools/                          [Tools] SDKs, MCP servers, CLIs, and libraries
│   └── benchmarks/                     [Benchmarks] independent and official evaluations
├── docs/site/                          bilingual documentation site
├── docs/jev/                           [AGENT] Jev knowledge base
├── src/decision_models/                the framework that runs an experiment
├── schema/                             dataset and result schemas
├── tests/                              tests for the framework
├── run.py                              CLI entry point
├── AGENTS.md                           [AGENT] project execution instructions
└── .claude/rules/                      [AGENT] project execution standard
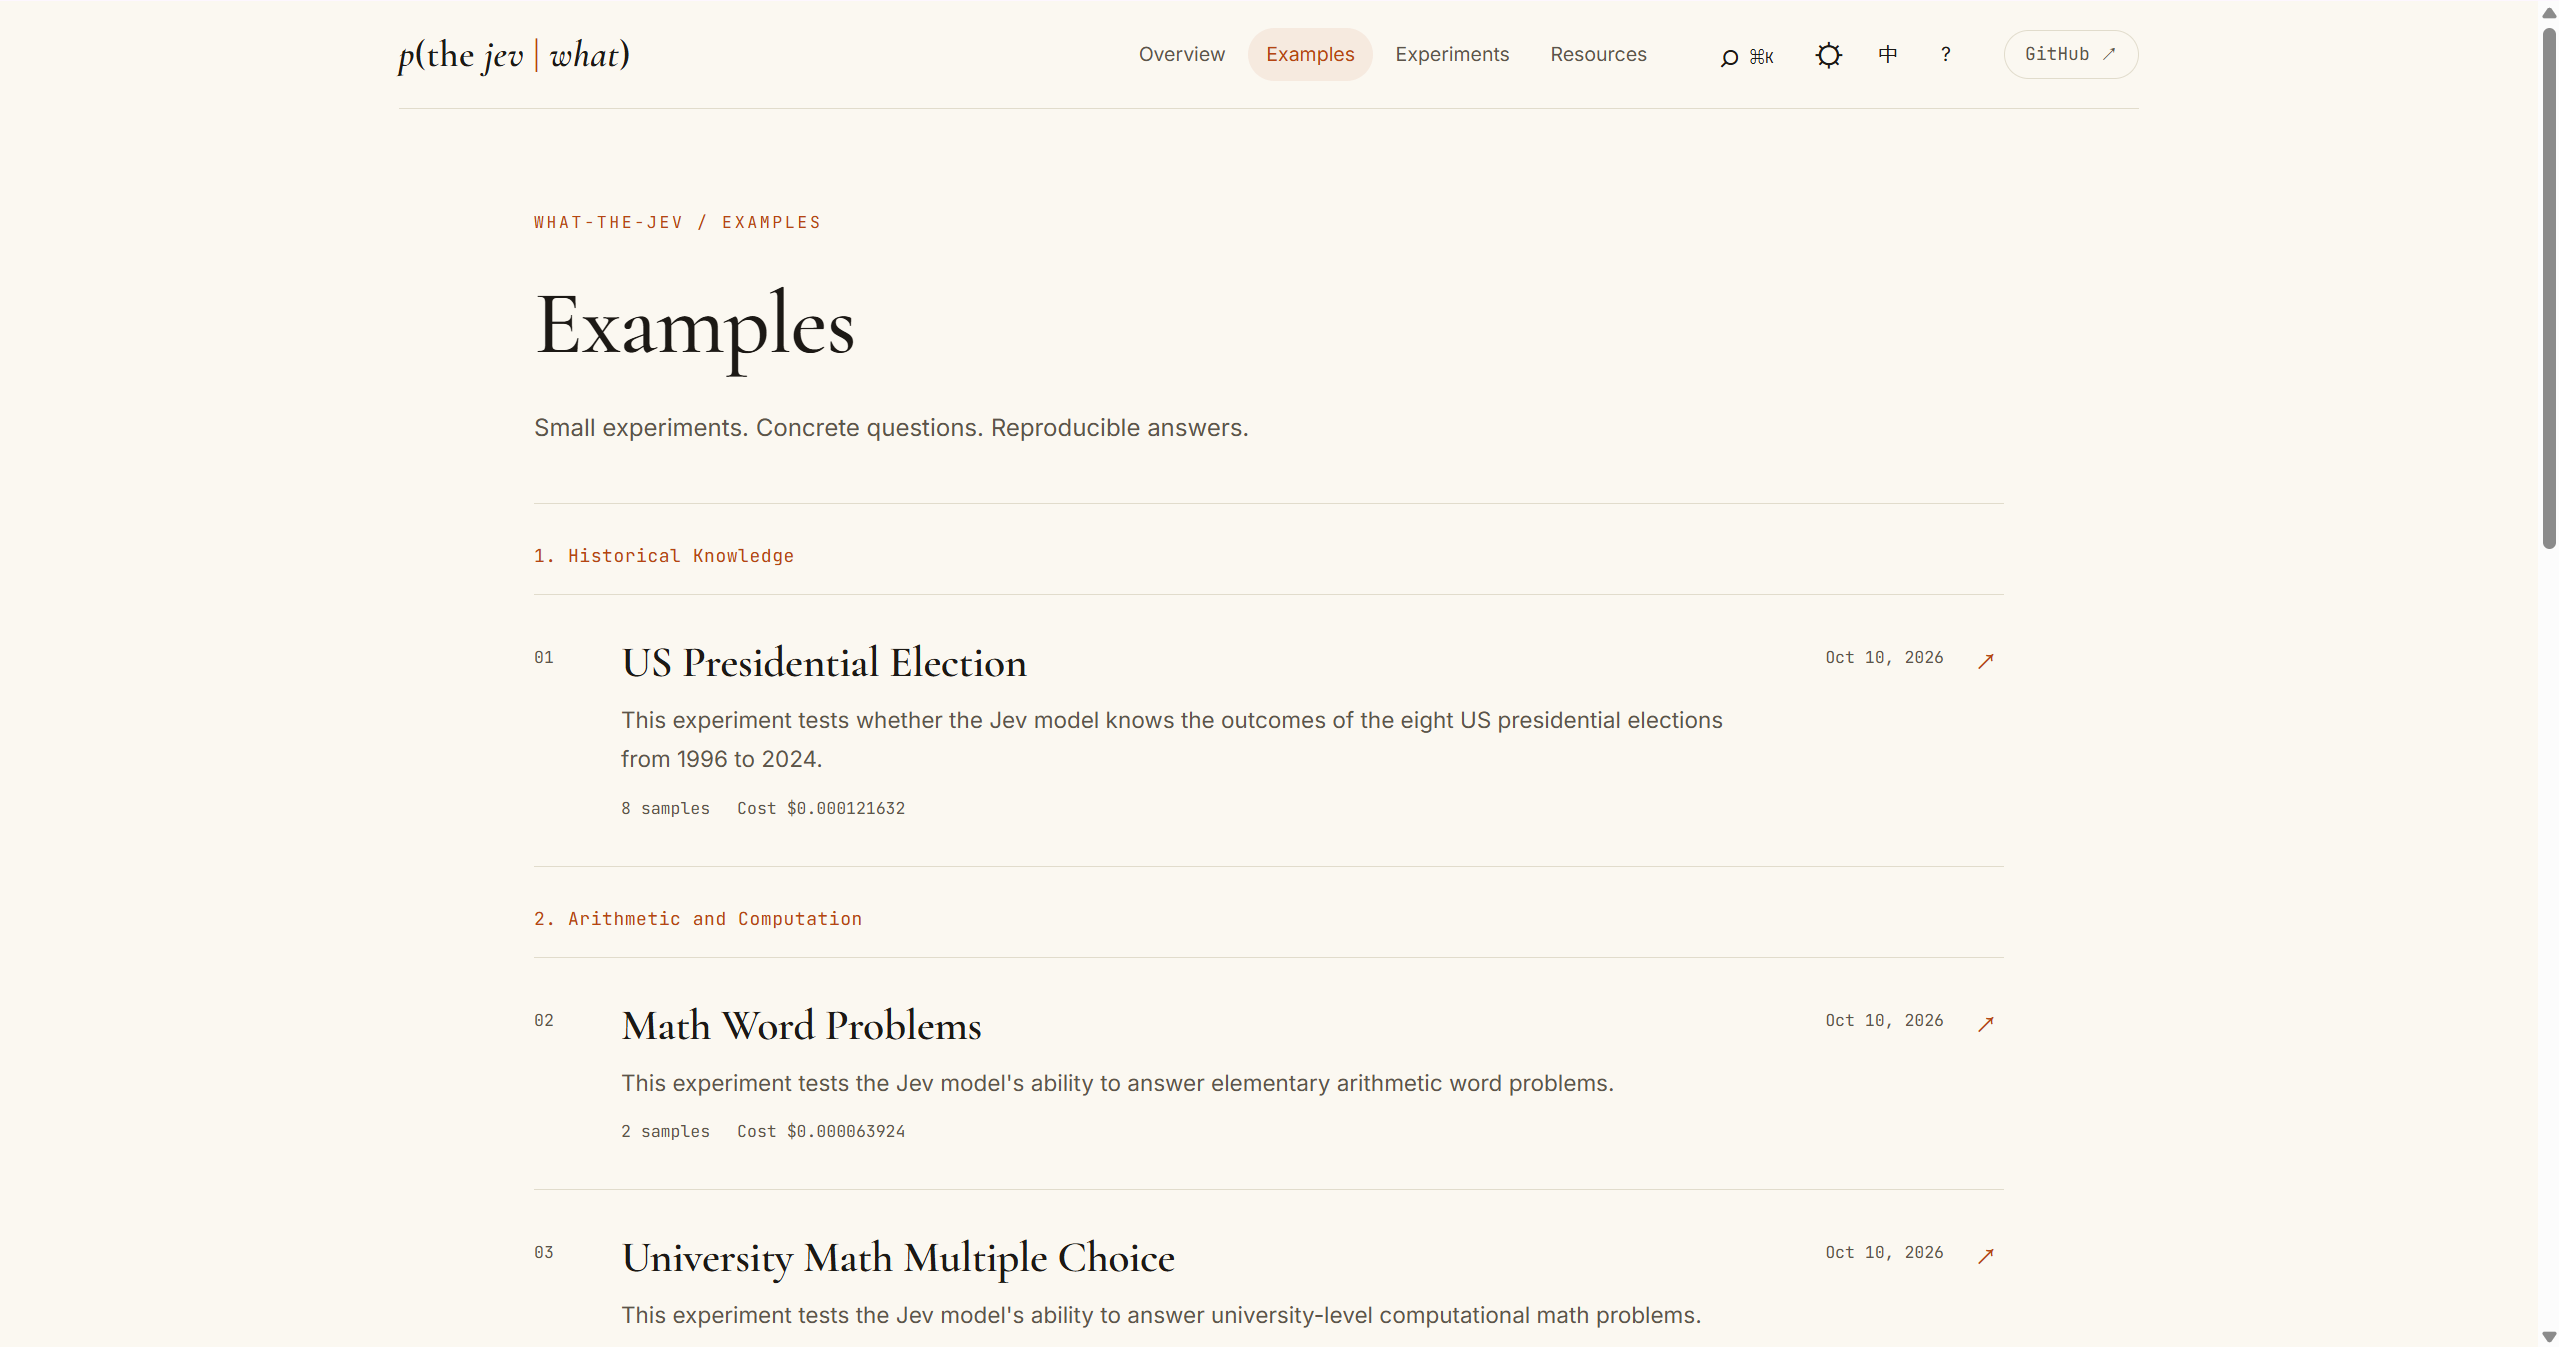
Lightweight examples
- Full index: example/INDEX.md
- Live site: Examples
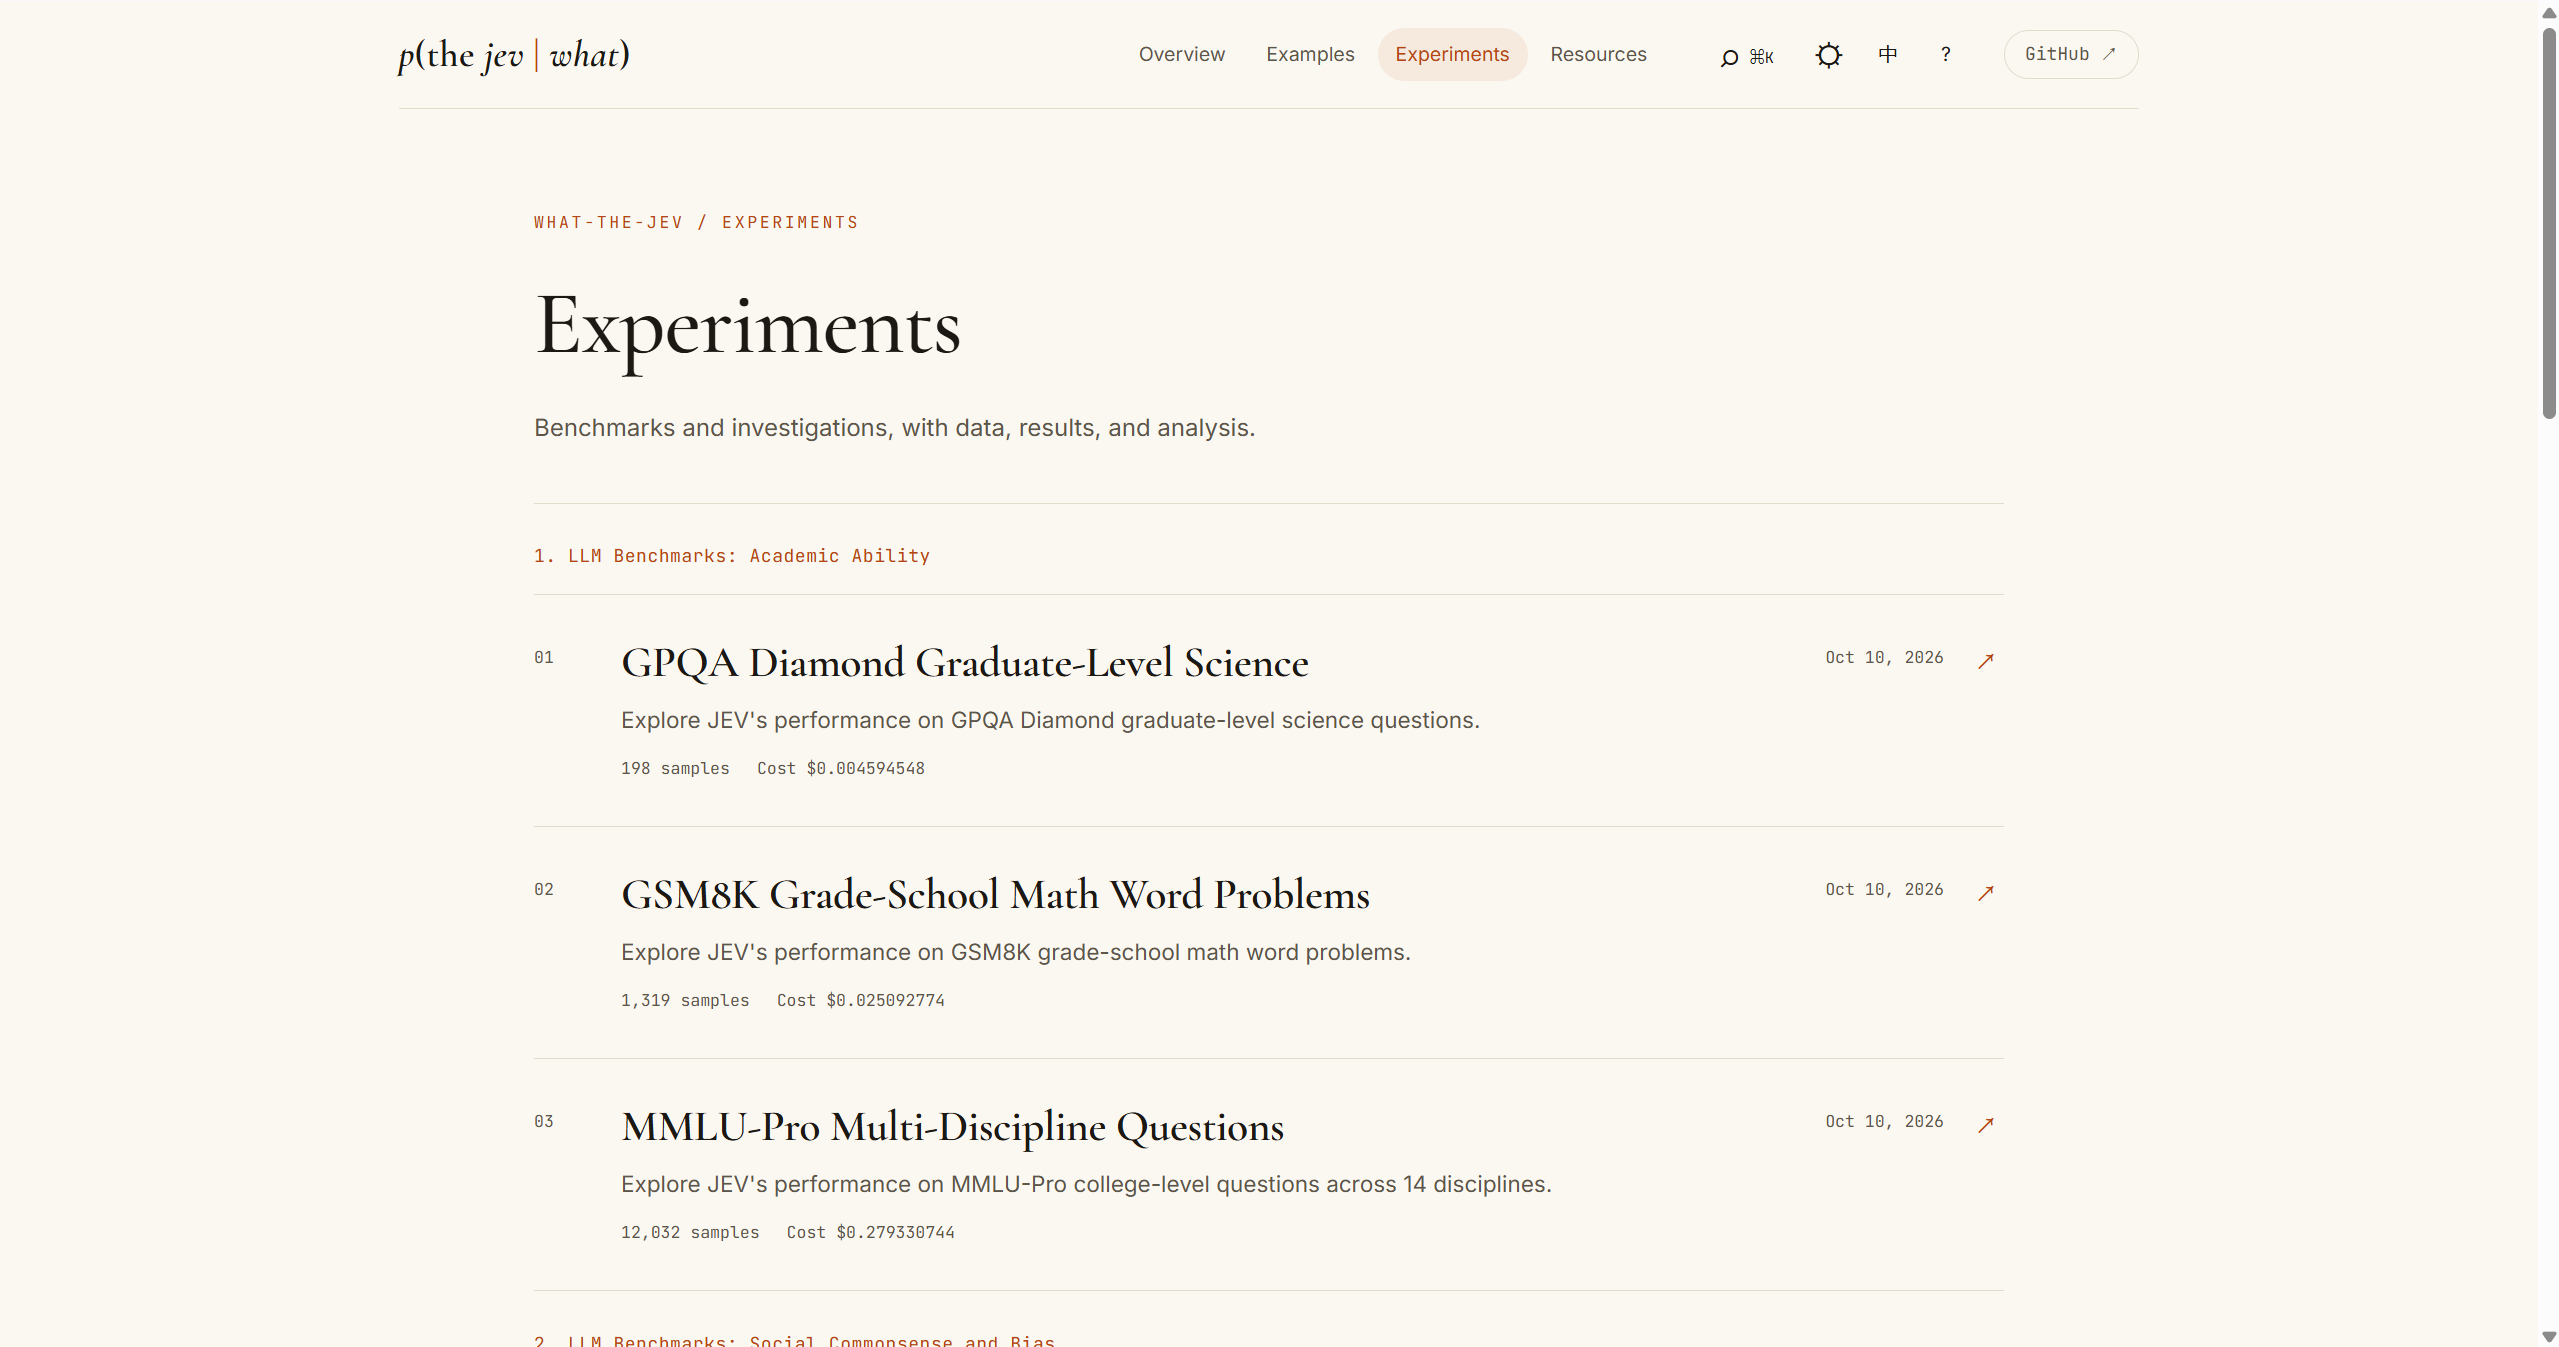
Experiments
- Full index: experiments/INDEX.md
- Live site: Experiments
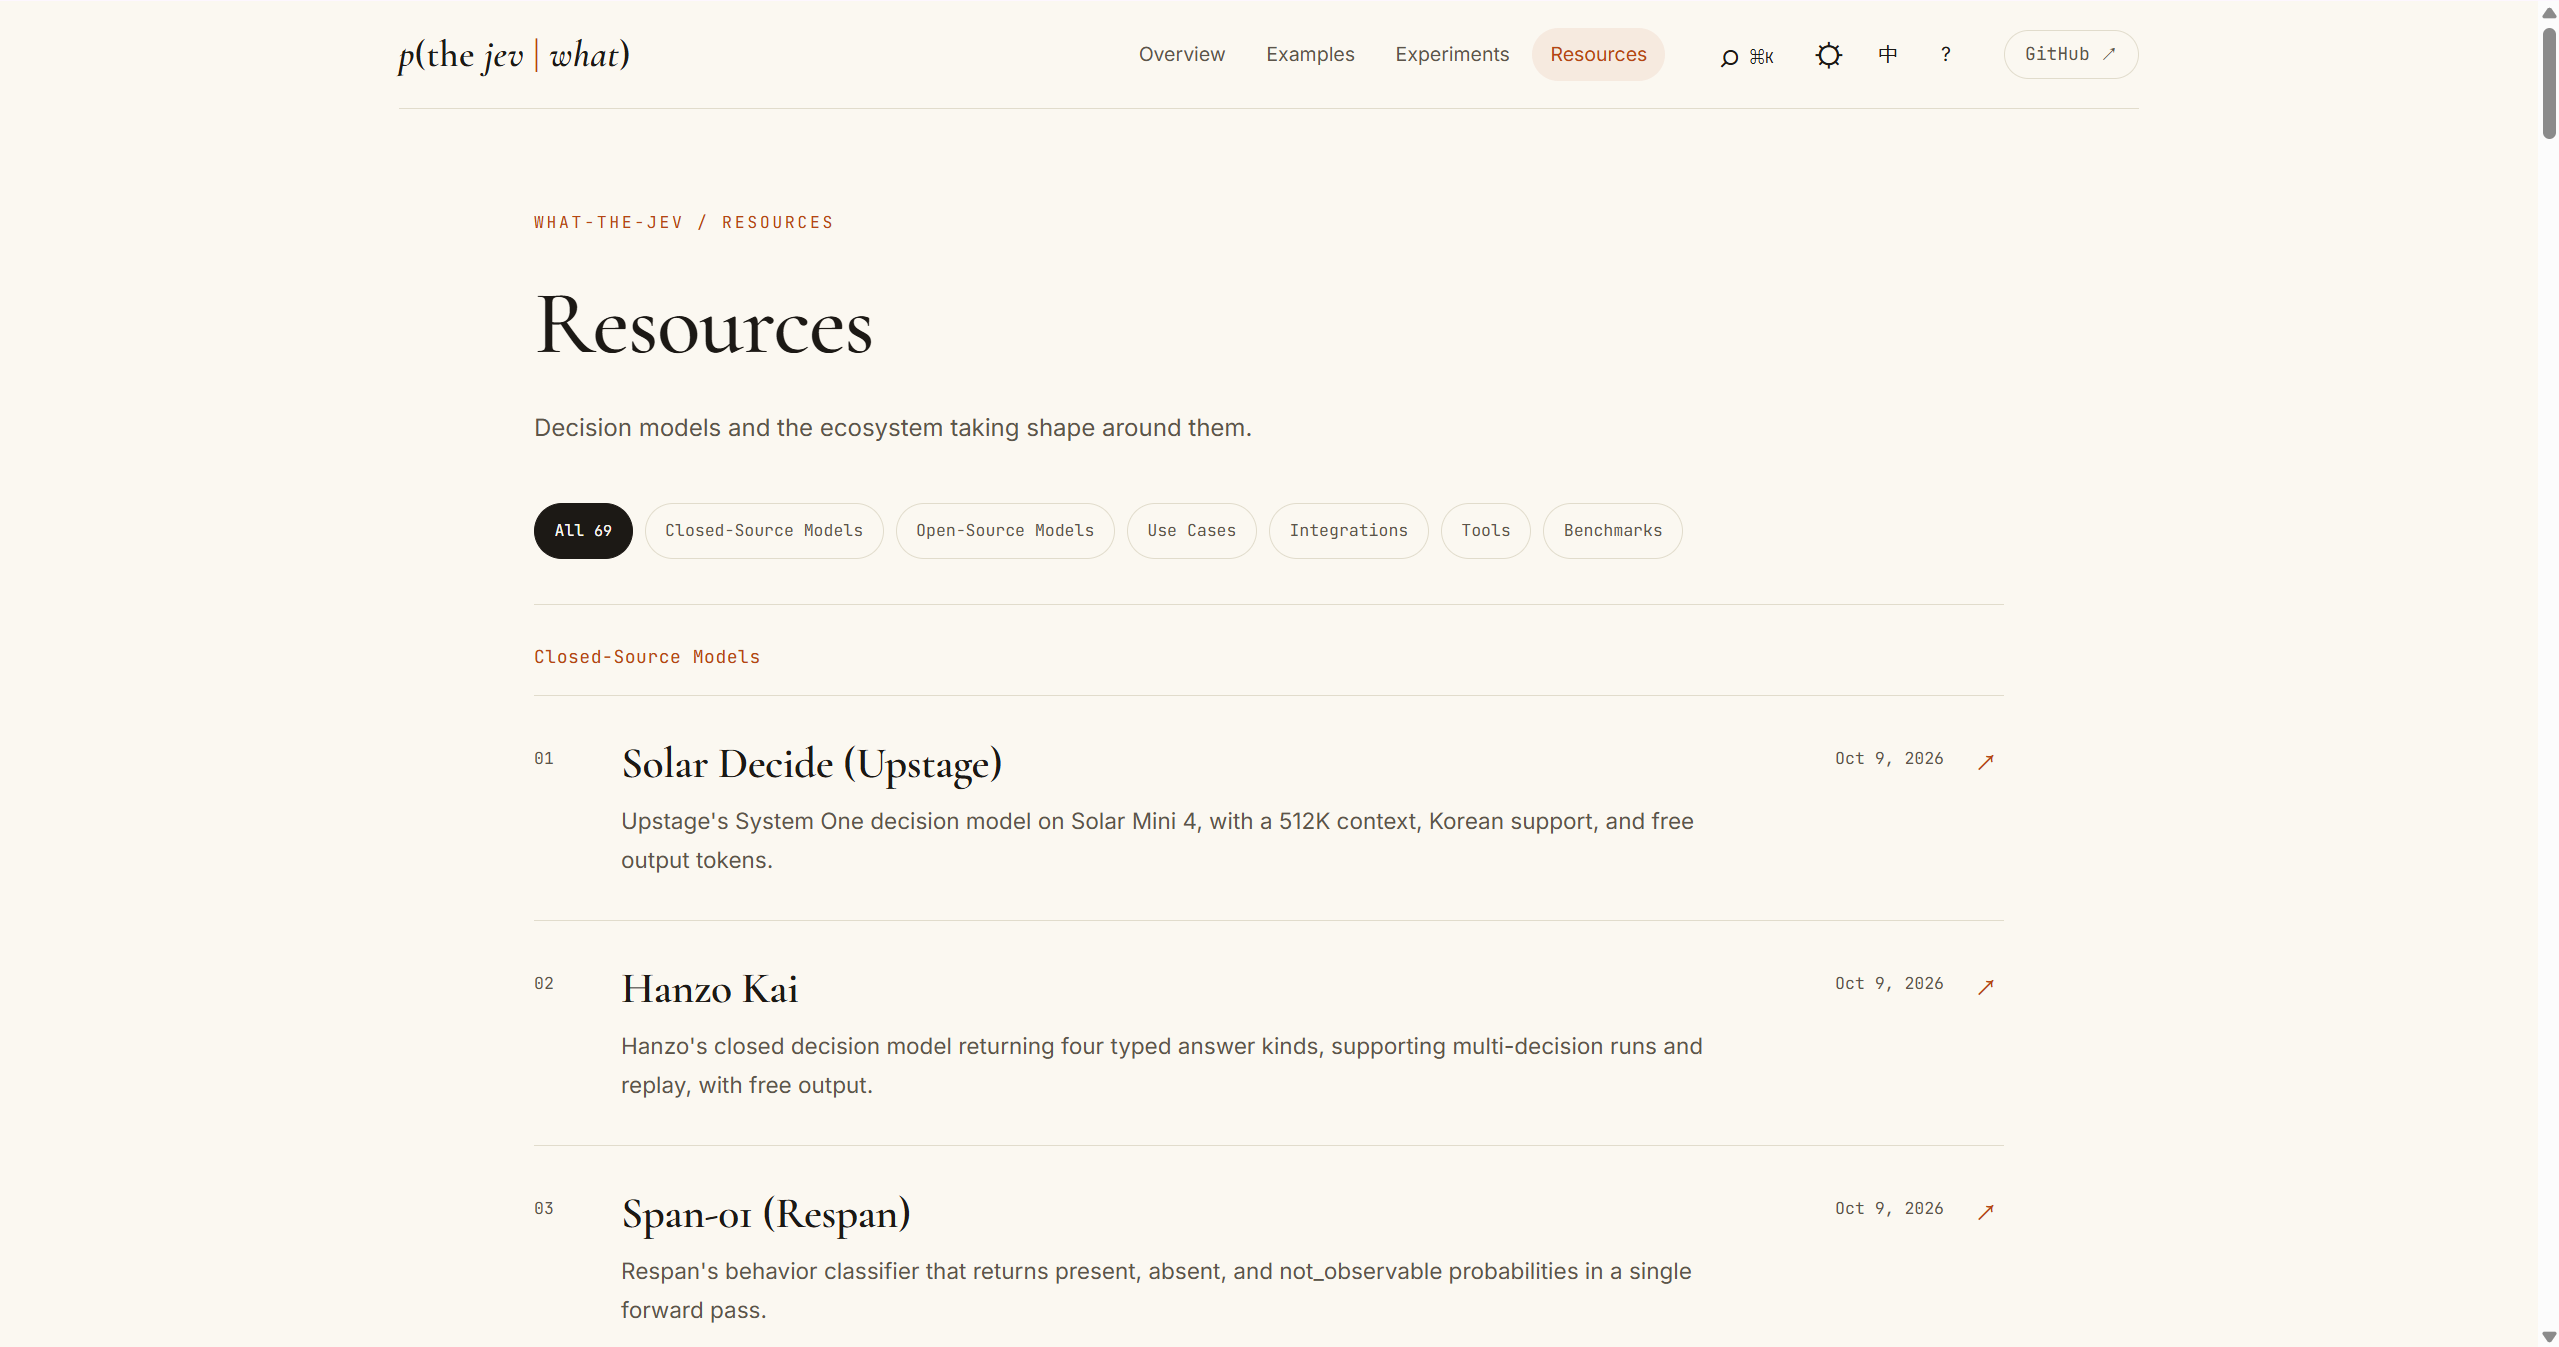
Resource catalog
- Full index: resource/README.md
- Live site: Resources
Start Here
You can ask your agent to clone this project with git clone --depth 1 https://github.com/keta1930/what-the-jev.git, then copy any of the prompts below to start exploring or running experiments.
1. Explore what Jev can do

Explain which Jev capabilities this project has explored and what limitations it has found. Recommend three examples or experiments suitable for getting started.

2. Run your first example

Help me run the ticket-triage example in example/ticket-triage. Check the runtime environment and API configuration, and tell me what I need to provide. After the run, explain the model's answers, result files, and API costs.

3. Evaluate your own task

I want to use Jev to: [describe your task].

Find relevant examples, experiments, and resources in this repository. Use the existing framework to design an experiment following the repository conventions. Validate it with a small number of samples first, then provide a reproducible experiment and an analysis report explaining its effectiveness, costs, and limitations.
Experiment results are saved as JSONL. To make them easier to read in VS Code, the project author also provides JSONL Native Reader, an extension that displays JSONL as a formatted JSON array. Search for JSONL Native Reader in the VS Code Extensions Marketplace.
Roadmap
We will continue exploring applications of decision models and improving the experimentation framework and interactive experience:
- Expand examples and experiments: Add more work to
example/andexperiments/, exploring decision models in research and commercial settings with reproducible experiments, results, and analysis reports. - Develop interactive games: Build experiments in
game/, each with its own frontend and support for replaying the experiment, making the decision process easier to follow and more engaging to play. This section has not yet been implemented. - Keep the resource catalog current: Maintain
resource/with decision-model-related models, tools, integrations, applications, and evaluations. - Strengthen the experiment infrastructure: Improve model integration and registration so more open-source decision models can run experiments within the same framework for reproduction, analysis, and comparison.
Track specific tasks and progress in Roadmap Issue #7. Discussion and contributions are welcome.
Contributing
Our goal is a decision-model community built entirely in the open-source spirit, exploring what decision models can be used for and where their capabilities end.
Any contribution is welcome: code, corrections, experiments or examples, resource entries, and more.
We look forward to your pull request.
Citation
If you use this repository, please cite it:
@software{what_the_jev,
  author = {{what-the-jev contributors}},
  title = {what-the-jev: Decision-model use cases and capability boundaries},
  url = {https://github.com/keta1930/what-the-jev},
  license = {MIT}
}
Contact
📧 Email: yandeheng1@gmail.com